You’re tasked with designing the data architecture that will power the future of your energy enterprise. It’s not just about storing data anymore. You need a platform that can ingest real-time streams from millions of smart meters, integrate decades-old SCADA systems, and serve as the foundation for AI that predicts grid failures and optimizes renewable generation. The challenge is immense, and the stakes—reliability, profitability, and sustainability—have never been higher.
Existing resources often miss the mark. They’re either too academic to be practical or they’re thinly veiled product pitches from a single vendor. You’re in the evaluation stage, and you need a vendor-neutral, architecturally sound blueprint, not a sales deck.
This guide provides that blueprint. We’ll walk through the core principles, architectural layers, and critical success factors for building a modern energy data platform that is not only powerful and scalable but also efficient and sustainable.
The Core Challenges You’re Facing in Energy Data
Building a robust data platform in the energy sector means confronting a unique set of challenges that go far beyond typical enterprise data problems. The big data analytics market in energy is set to more than double, from $11.42 billion in 2026 to $26.47 billion by 2034, and overcoming these hurdles is key to capturing that value.
Data Integration Complexities
You’re dealing with a tangled web of sources: real-time SCADA and IoT sensor data, historical data from OSI PI historians, geospatial information, weather forecasts, and market pricing data. Many legacy systems lack modern APIs, creating a significant integration debt that can stall projects before they even begin.
Data Quality and Trust
In an environment where a single bad data point could impact grid stability, data quality is non-negotiable. You constantly battle incomplete or delayed data from intermittent renewables, sensor drift that skews readings over time, and a lack of semantic interoperability between systems that call the same thing by different names.
Unprecedented Scale and Performance
The sheer volume and velocity of data are staggering. With over 135 million smart meters in the U.S. alone generating up to 54 petabytes of new data annually, your architecture must handle massive real-time ingestion and processing without faltering. Sub-second latency isn’t a “nice-to-have”; for grid management, it’s a requirement.
The Hidden Cost: Your Data’s Environmental Footprint
There’s a growing awareness of a critical, often-overlooked challenge: the energy consumption of data infrastructure itself. U.S. data centers consumed an estimated 176 TWh in 2023—nearly 4.5% of the country’s total electricity. With AI workloads expected to drive that demand exponentially, building a “green” data architecture is no longer just an ethical consideration; it’s a core operational and financial imperative.
The Modern Energy Data Platform: Architectural Blueprint
To solve these challenges, you need to move beyond traditional data warehouses and monolithic systems. The future is a modular, vendor-neutral, and sustainable architecture. The guiding principles are simple: build for flexibility, design for real-time, govern with federation, and prioritize efficiency at every layer.
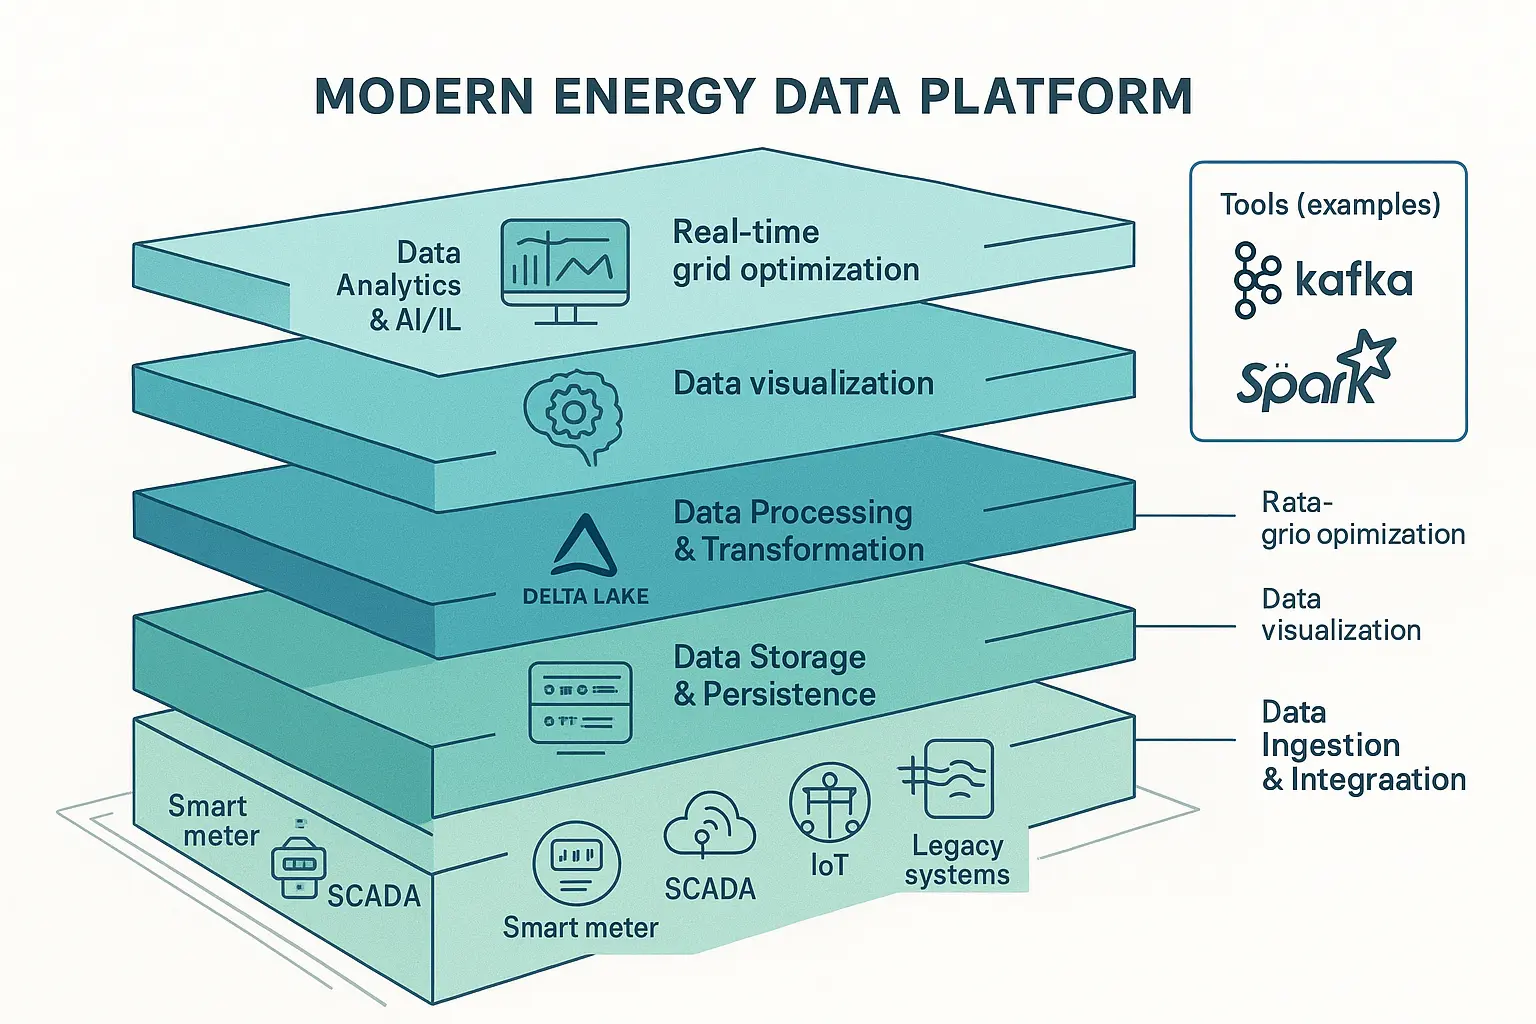
Layer 1: Data Ingestion & Integration
This layer is the gateway for all data. A successful strategy uses a dual approach to handle the variety and velocity of energy data.
- Real-time Streaming: For sensor, grid, and market data, technologies like Apache Kafka, Azure IoT Hub, or MQTT brokers are essential. They provide low-latency, high-throughput pipelines for data that can’t wait.
- Batch Ingestion: For less time-sensitive sources like ERP systems, historical billing data, or weather models, traditional ETL/ELT tools (like Fivetran or Airbyte) can efficiently pull data on a scheduled basis.
- Legacy Systems: Don’t rip and replace. Use API gateways, data virtualization tools, or incremental migration strategies to bridge the gap between legacy OT systems and your modern cloud platform.
Layer 2: Data Storage & Persistence (The Lakehouse Foundation)
A modern Lakehouse architecture offers the best of both worlds: the low-cost, flexible storage of a data lake with the performance and governance features of a data warehouse.
- Data Lake (Storage): Use object storage like Amazon S3 or Azure Data Lake Storage (ADLS) Gen2 as your landing zone for all raw data, in any format. This ensures you capture everything without needing a predefined schema.
- Structured Layer (Warehouse): Implement an open table format like Delta Lake or Apache Iceberg on top of your data lake. This provides ACID transactions, schema enforcement, and time travel capabilities, making your raw data reliable for BI and analytics.
- Sustainability Focus: Implement intelligent storage tiering. Automatically move older, less-frequently accessed data to cheaper, lower-energy archival tiers. Enforce strict data retention policies to avoid storing petabytes of redundant data indefinitely.
Layer 3: Data Processing & Transformation
Here, raw data is cleaned, enriched, and structured for analysis.
- Stream Processing: For use cases like real-time anomaly detection or intraday forecasting, leverage frameworks like Apache Flink or Spark Streaming. They process data in motion, enabling near-instantaneous insights for critical operations. Achieving truly effective real-time grid optimization depends on mastering this layer.
- Batch Processing: For large-scale transformations, AI model training, or complex aggregations, Apache Spark remains the industry standard, offering unparalleled performance and scalability.
Layer 4: Data Analytics & AI/ML
This is where your data creates value. This layer must empower everyone from data scientists to business analysts.
- AI/MLOps: Provide data science workbenches (like Databricks or SageMaker) with integrated feature stores and MLOps capabilities. This streamlines the entire lifecycle from model training and deployment to monitoring, which is crucial for applications like predictive maintenance for wind turbines.
- BI & Reporting: Connect tools like Power BI or Tableau directly to your governed Lakehouse layer for fast, reliable business intelligence and operational reporting.
- Sustainability Focus: Choose energy-efficient AI models and optimize your training infrastructure. Often, a slightly less complex model can provide 99% of the accuracy for 50% of the computational (and energy) cost.
Layer 5: Data Access & Consumption
The final layer makes your data products accessible to applications and users.
- APIs & Data Services: Expose curated, high-quality datasets through well-documented APIs (REST, GraphQL) so developers can easily build new applications.
- Data Catalog & Marketplace: Implement a data catalog for self-service discovery. This empowers domain experts to find, understand, and use the data they need without going through IT bottlenecks.
Implementing Trust: Data Quality, Governance & Security
An architecturally sound platform is useless if the data within it can’t be trusted. Trust is built on a foundation of robust quality, governance, and security practices that are designed for the complexities of a distributed energy ecosystem.
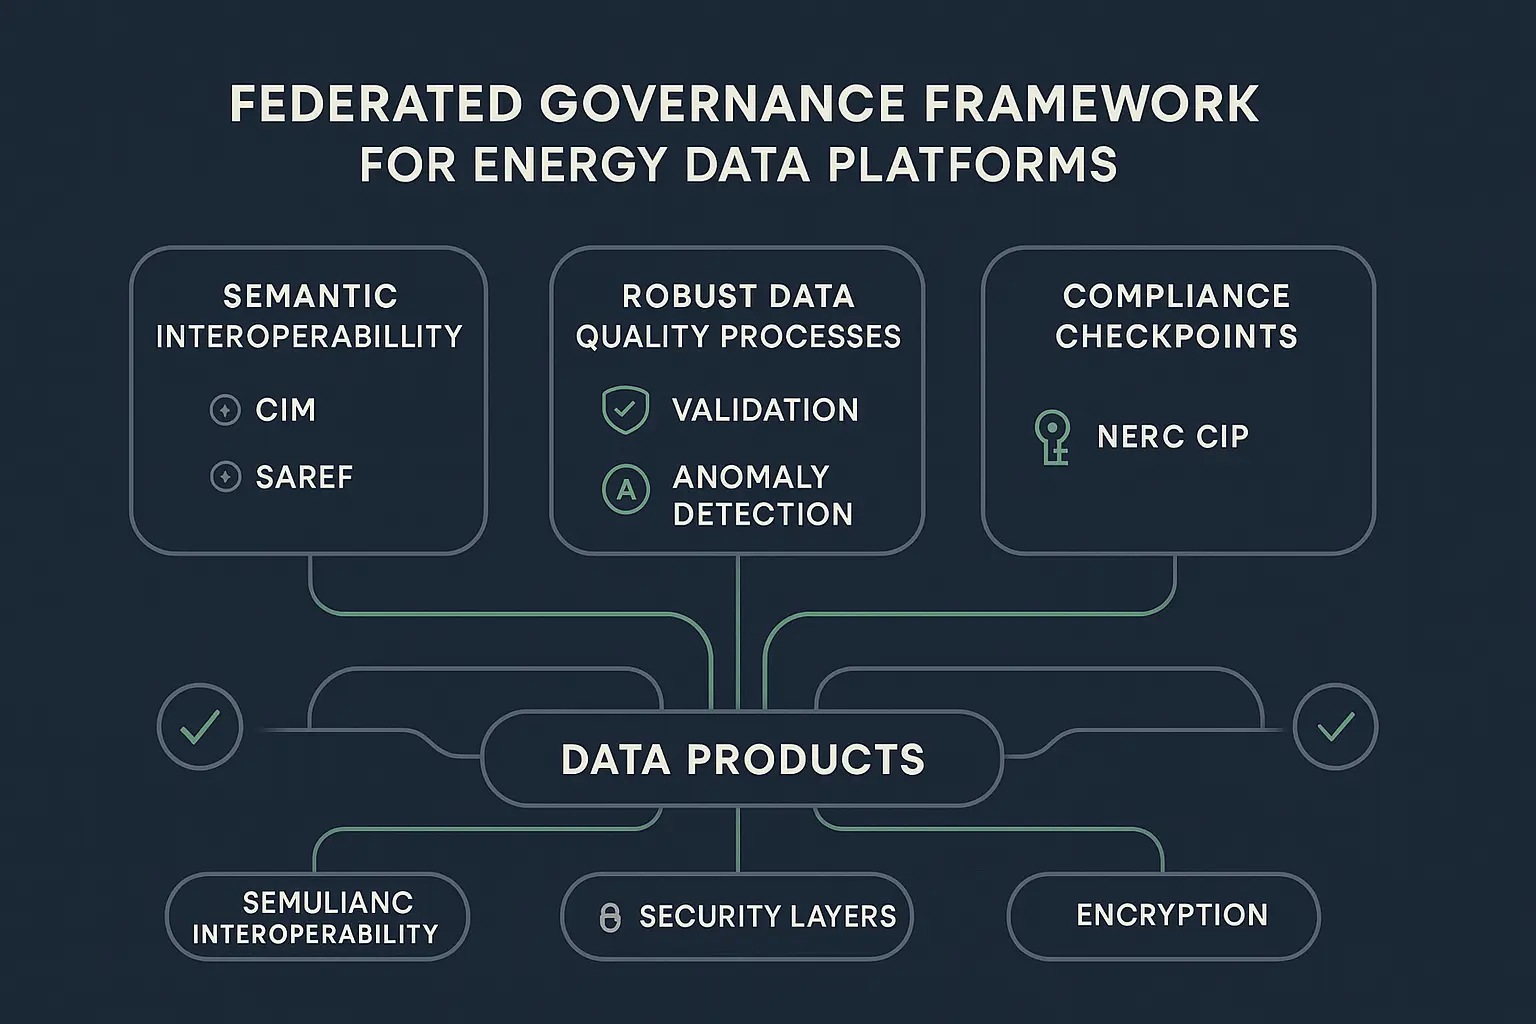
- Achieve Semantic Interoperability: Don’t just store data; store meaning. Adopt standardized data models like the Common Information Model (CIM) to ensure that a “substation” in one system means the same thing in another.
- Embrace Federated Governance: A centralized governance team can’t possibly understand the context of every dataset. Implement Data Mesh principles by assigning domain ownership. The team that generates the grid data is responsible for its quality, accessibility, and documentation, treating it as a “data product.”
- Automate Data Quality: Manually checking data quality at this scale is impossible. Implement automated data quality frameworks with validation rules, ML-driven anomaly detection to catch sensor drift, and comprehensive data profiling at the point of ingestion.
- Ensure Security by Design: The energy sector is critical infrastructure. Enforce strict role-based access control (RBAC), end-to-end encryption, and build for compliance with standards like NERC CIP from day one.
The “Green” Data Platform: Architecting for Sustainability
Designing for sustainability is a paradigm shift. Instead of treating performance and cost as the only metrics, you must add energy efficiency as a core design principle. This isn’t just about being eco-friendly; it’s about building a more cost-effective and resilient platform.
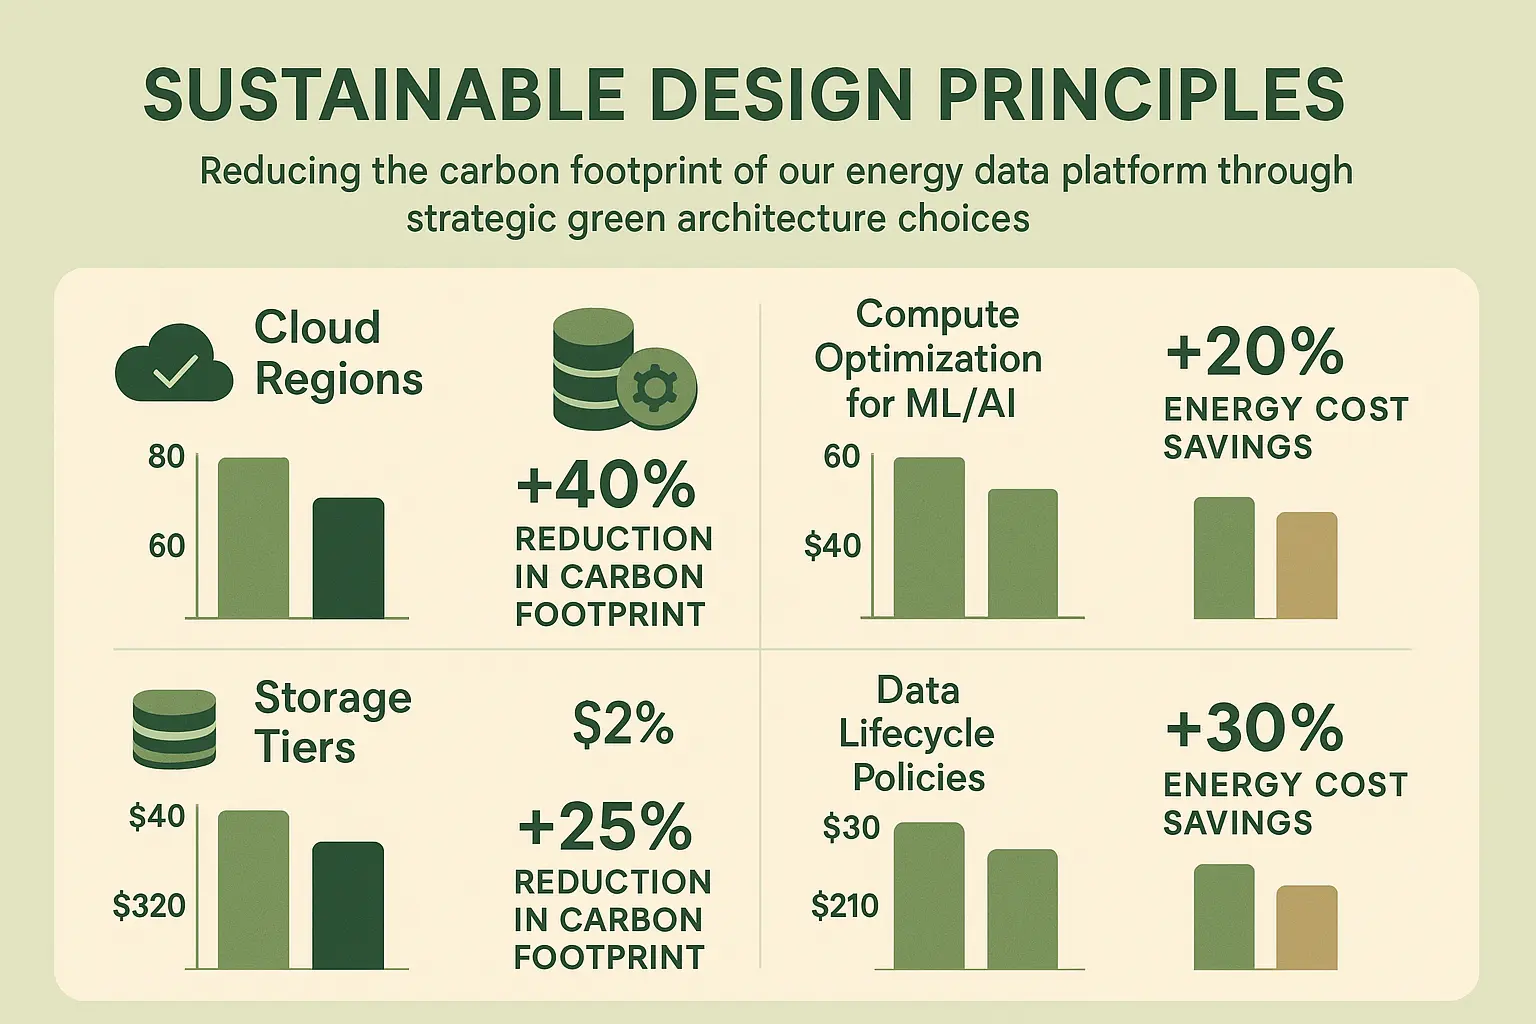
Three Levers for a Greener Architecture
- Optimized Cloud Infrastructure: Choose cloud regions powered by renewable energy. Aggressively right-size your virtual machines and use serverless computing where possible to avoid paying for—and powering—idle resources.
- Data Storage Efficiency: Your storage strategy has a direct impact on energy consumption. Beyond intelligent tiering, use efficient data formats like Parquet and implement aggressive compression and deduplication to reduce your overall storage footprint.
- Compute Optimization: Run large-scale batch processing and AI training jobs during off-peak hours when the grid is cleaner and energy is cheaper. Focus on code and query efficiency—a poorly optimized SQL query running for an hour consumes far more energy than a well-written one that runs in two minutes. Start by understanding your baseline with a carbon footprint calculator for data operations.
Roadmap & Implementation Strategy for Data Architects
Adopting this architecture is a journey, not a single project. A phased approach allows you to demonstrate value quickly, build momentum, and de-risk the transformation.
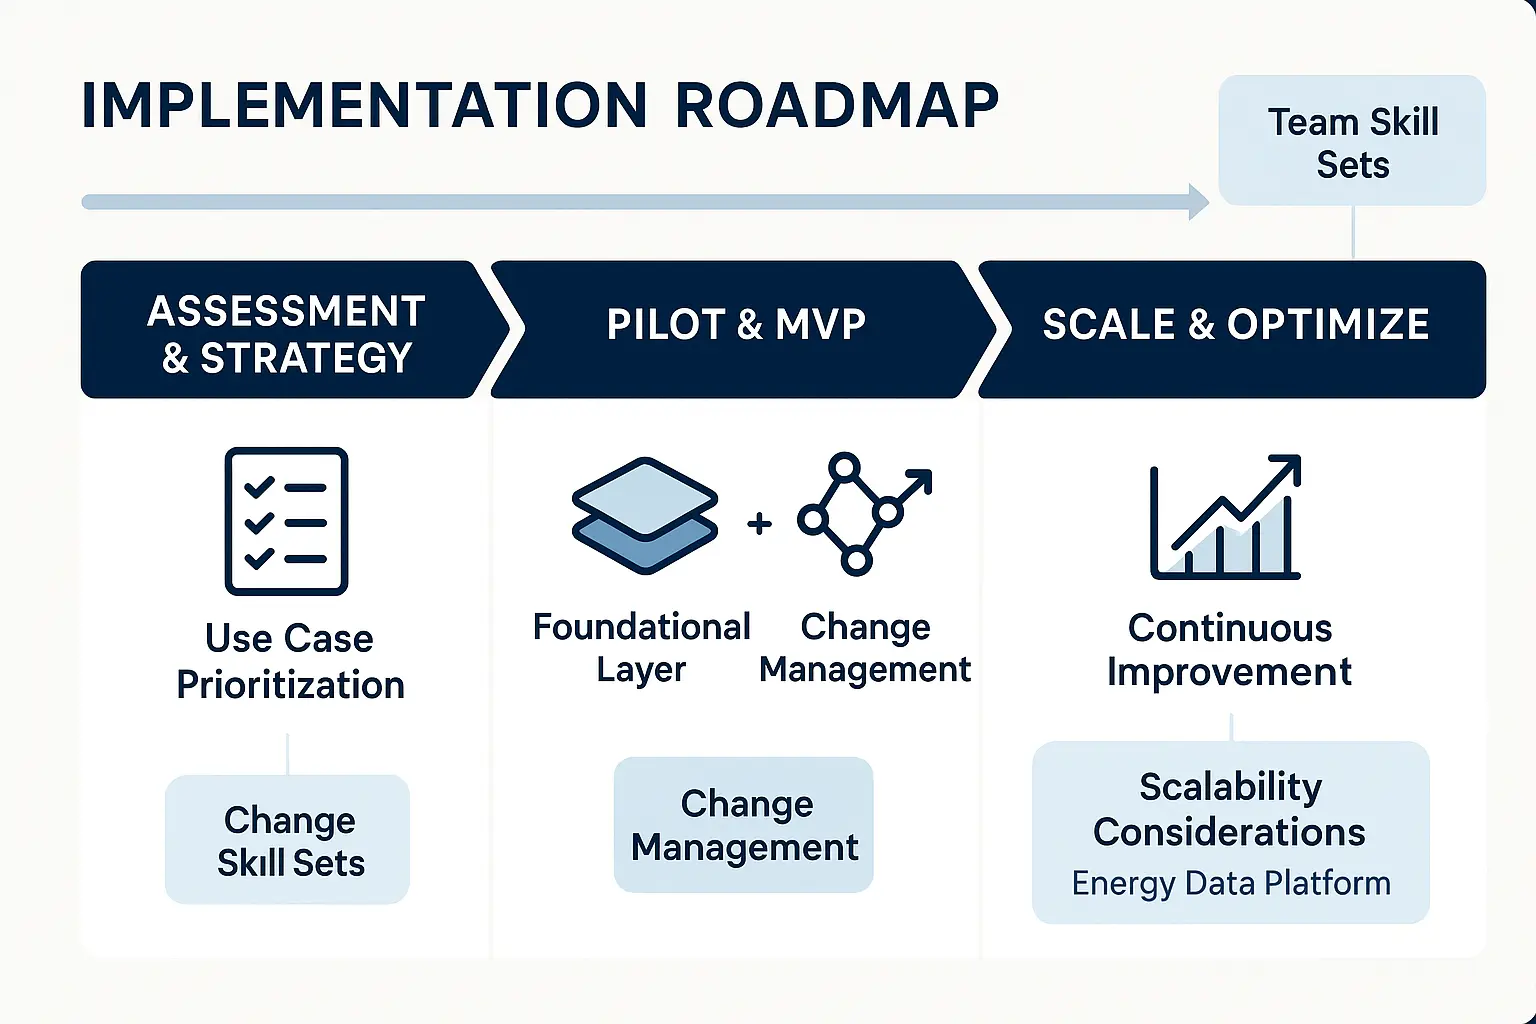
- Phase 1: Assessment & Strategy (Months 1-3): Analyze your current data landscape and identify the most critical business use cases. Prioritize one or two high-impact projects, like real-time monitoring for a key substation or demand forecasting for a specific region.
- Phase 2: Pilot & MVP (Months 4-9): Build the foundational layers of the platform for your pilot use case. Focus on getting the ingestion, Lakehouse storage, and basic processing pipelines running. Prove the value and technical feasibility to secure broader buy-in.
- Phase 3: Scale & Optimize (Months 10+): Once the MVP is successful, begin onboarding additional data domains and use cases. Enhance your MLOps capabilities, refine your governance model, and continuously optimize for cost, performance, and energy efficiency.
Frequently Asked Questions for Architects
1. How does a Lakehouse really compare to our existing enterprise data warehouse for energy analytics?A traditional data warehouse requires you to define a rigid schema before you load data, which is slow and inflexible for the diverse data types in energy (like unstructured sensor logs or image data from drone inspections). A Lakehouse lets you store all raw data in a cost-effective data lake first, then apply structure and governance on top. This provides the flexibility to handle any data type while still delivering the performance and reliability needed for critical BI and SQL analytics.
2. What’s the best architectural pattern for integrating legacy OT data from systems like OSI PI or SCADA?Avoid a “big bang” migration. A highly effective pattern is to use a data replication or streaming agent at the edge, close to the source system. This agent can capture data changes in real-time and stream them into your cloud ingestion layer (e.g., Kafka). This decouples the legacy system from the cloud platform, minimizes impact on OT operations, and provides a steady stream of data to the new architecture without requiring a full system replacement upfront.
3. Is a Data Mesh architecture too complex for an organization just starting its cloud data journey?You don’t have to implement a full Data Mesh from day one. Start with the core principle: federated ownership. For your first pilot project, identify the business domain that owns the source data and make them a partner in the project. Treat the dataset you’re building as a “data product,” with a clear owner, documentation, and quality standards. This plants the seed for a Data Mesh culture without the upfront complexity of a full-scale implementation.
4. How can we realistically measure the carbon footprint and energy consumption of our data platform?Start with what the cloud providers offer. Major providers like AWS, Azure, and GCP have tools (like the Customer Carbon Footprint Tool) that estimate the emissions associated with your cloud usage. While not perfect, they provide a valuable baseline. For a more granular view, you can start tagging resources by project or business unit and correlate cloud costs (which are a proxy for resource consumption) with the provider’s carbon data. This allows you to identify high-consumption workloads and prioritize them for optimization.
Your Architecture is Your Strategy
Building a modern energy data platform is one of the most strategic investments you can make. It’s the foundation for a more intelligent, resilient, and sustainable energy future. The right architecture will unlock new revenue streams, drive massive operational efficiencies, and empower your organization to lead in the energy transition.
When you’re ready to move from blueprint to build, it helps to have a partner who understands both the architectural patterns and the unique demands of the energy sector.
Ready to discuss how these architectural principles can be applied to your specific challenges? Schedule a consultation with one of our expert data architects today.