You’re evaluating AI voice agents, and the market is a sea of acronyms and bold claims. Every provider promises “human-like” conversation, but what does that actually mean? The difference between a frustrating chatbot and a truly effective AI agent isn’t in the marketing—it’s in the core technology. Making the right choice requires looking under the hood.
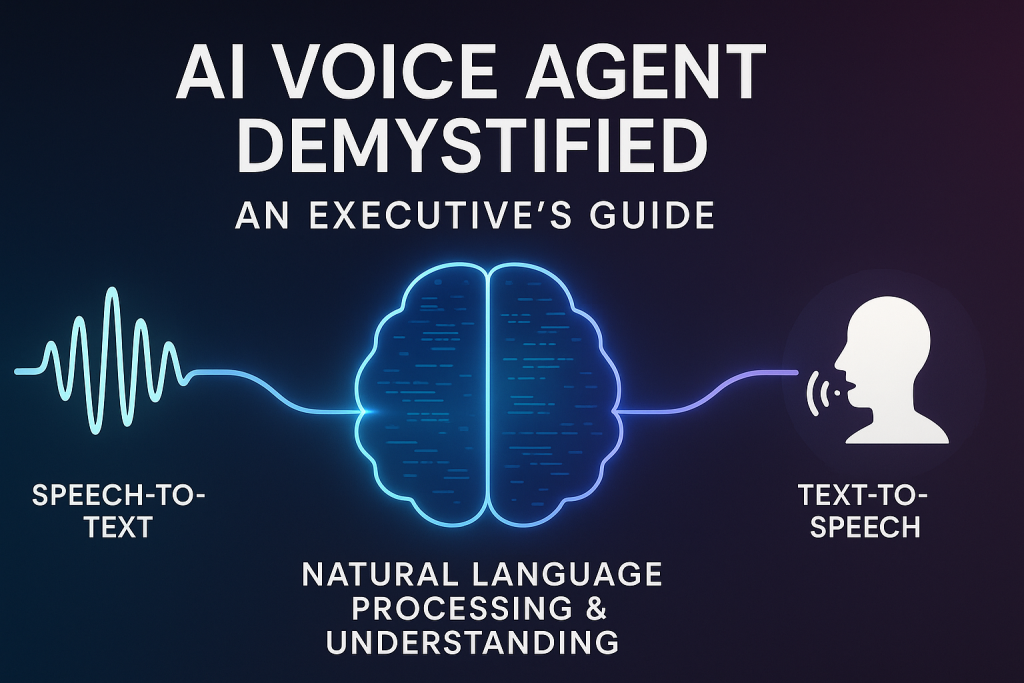
With 80% of businesses planning to implement AI-driven voice technology by 2026, understanding this technology is no longer optional; it’s a competitive necessity. This guide breaks down the four fundamental pillars of modern voice AI: Speech-to-Text (STT), Natural Language Processing & Understanding (NLP/NLU), and Text-to-Speech (TTS). We’ll move beyond the buzzwords to give you the framework you need to evaluate solutions, ask the right questions, and invest with confidence.
Chapter 1: Speech-to-Text (STT) – Decoding Human Language
Everything starts here. An AI agent can’t understand what it can’t hear correctly. Speech-to-Text, also known as Automatic Speech Recognition (ASR), is the foundational process of converting spoken audio into machine-readable text. While it sounds simple, the accuracy of this single step has a cascading effect on the entire user experience.
Technical Deep Dive: The Engines of Transcription
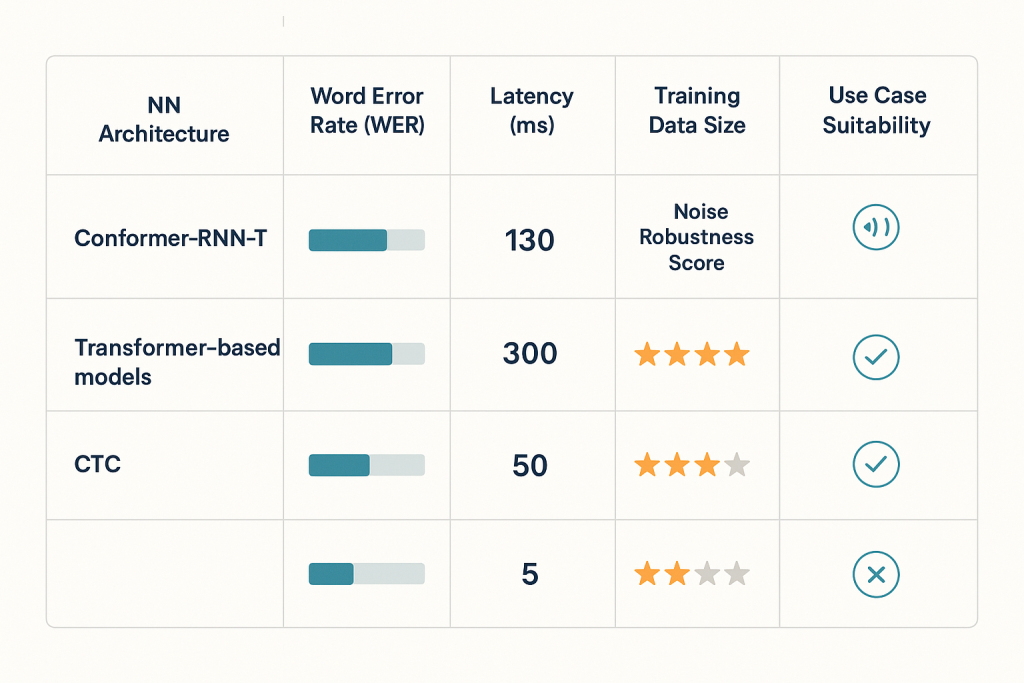
Modern STT isn’t just about matching sounds to words; it’s about understanding context, filtering noise, and predicting sequences. This is achieved through sophisticated neural network architectures.
- Conformer & Transformer-based Models: These are the current state-of-the-art. Unlike older models, they excel at capturing both local features (the sound of a single word) and long-range context (how that word relates to the rest of the sentence). This dramatically improves accuracy, especially for complex or ambiguous phrases.
- End-to-End (E2E) Models: These systems streamline the process by directly mapping raw audio to text in a single neural network. This reduces latency and complexity, making them ideal for the real-time conversations your customers expect.
The Real-World Challenge: Improving STT Accuracy in Noisy Environments
The most significant challenge for STT is background noise. A call from a busy street, a factory floor, or a crowded café can introduce audio artifacts that cripple less advanced systems. This leads to high Word Error Rates (WER), the primary metric for STT performance. As research from institutions like Taylor & Francis highlights, diverse noise types and reverberation remain significant technical hurdles.
To combat this, leading STT solutions employ advanced techniques:
- Spectral Subtraction: A process that identifies and removes stable background noise from the audio signal.
- Beamforming: Uses multiple microphones to focus on the speaker’s voice while filtering out sounds from other directions.
- Robust Feature Extraction: Models are trained to identify the essential characteristics of speech, even when parts of the audio signal are obscured by noise.
When evaluating a solution, don’t just ask if it handles noise—ask how. Understanding their approach to noise reduction is critical for any real-world application.
Chapter 2: Natural Language Processing (NLP) & Understanding (NLU) – The Brain of the Agent
Once speech is converted to text, the AI agent needs to comprehend its meaning. This is the domain of Natural Language Processing (NLP) and its critical subfield, Natural Language Understanding (NLU).
- NLP is the broad field of enabling computers to process and analyze large amounts of human language data.
- NLU is where the magic happens. It focuses on deciphering the intent behind the text. What does the user want to achieve?
An NLU model breaks down a user’s request into two key components:
- Intent: The user’s primary goal (e.g., check_order_status).
- Entities: The key pieces of information needed to fulfill the intent (e.g., order_number: “12345”).
Technical Deep Dive: The Role of LLMs in Generative AI Voice Responses
The biggest leap in NLU has been the integration of Large Language Models (LLMs). Early NLU systems were rigid, relying on predefined rules and examples. LLMs, built on Transformer architectures like BERT, have changed the game. They provide a deep, contextual understanding of language that allows AI agents to:
- Handle Ambiguity: Understand nuanced or poorly phrased requests without failing.
- Manage Complex Dialogues: Maintain context over multiple conversational turns, remembering previous statements to inform current responses.
- Go Beyond Basic Intent: NLU is now evolving to capture tone, sarcasm, and even shifts in user intent mid-conversation.
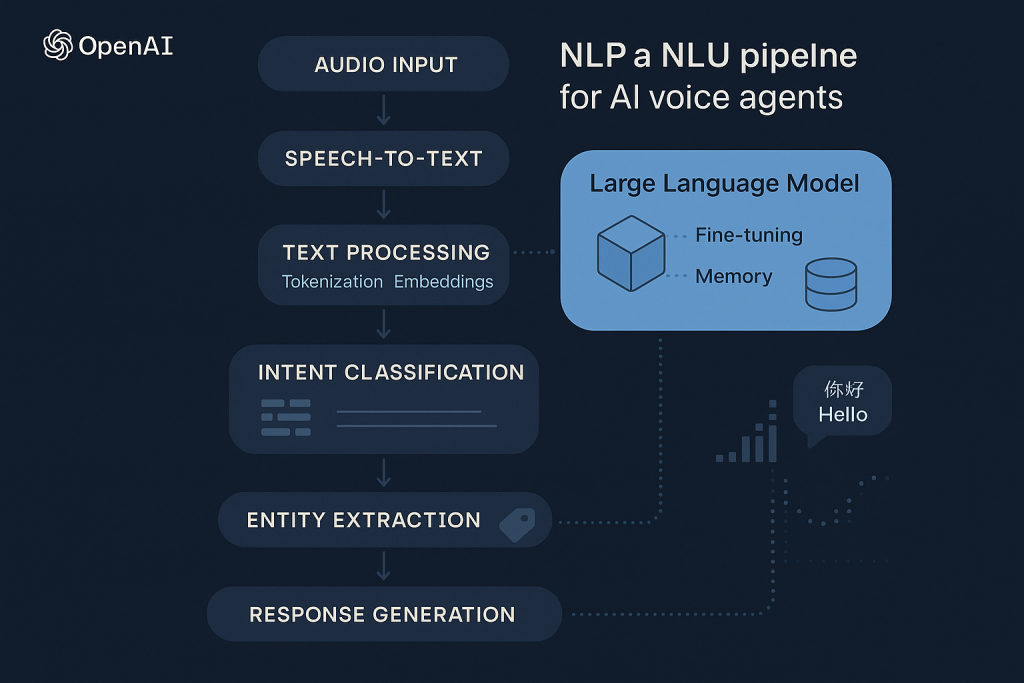
Effective LLM integration isn’t just about connecting to an API. It involves sophisticated architectural patterns like Retrieval-Augmented Generation (RAG), which allows the model to pull in real-time information from your knowledge base, and fine-tuning, which adapts the model to your specific business domain and vocabulary. This is a key area where can make a significant difference.
Chapter 3: Text-to-Speech (TTS) – Crafting Human-Like Voices
The final piece of the puzzle is the agent’s voice. Text-to-Speech (TTS) technology converts text back into spoken audio. The quality of the TTS engine is what your customers will notice most—it defines the agent’s personality and determines whether the interaction feels natural or robotic.
The standard for quality is now incredibly high. Research shows that up to 65% of consumers cannot distinguish modern AI narration from a human voice. This is thanks to neural TTS.
Technical Deep Dive: The Two-Stage Paradigm
Modern, high-fidelity TTS systems typically use a two-part process:
- Spectrogram Generation: A neural network like Tacotron 2 or FastSpeech converts the input text into a spectrogram—a visual representation of sound frequencies. This stage determines pronunciation, cadence, and intonation.
- Vocoding: A neural vocoder, such as WaveNet or HiFi-GAN, then synthesizes an audio waveform from that spectrogram. This stage generates the raw, audible sound, adding the richness and texture that make a voice sound realistic.
This approach is crucial for Designing Human-Like TTS for Customer Interactions. It allows for fine-grained control over prosody (the rhythm and stress of speech) and emotional inflection, moving beyond monotone responses to conversations that convey empathy and understanding.
Open-Source vs. Proprietary: A Key Strategic Decision
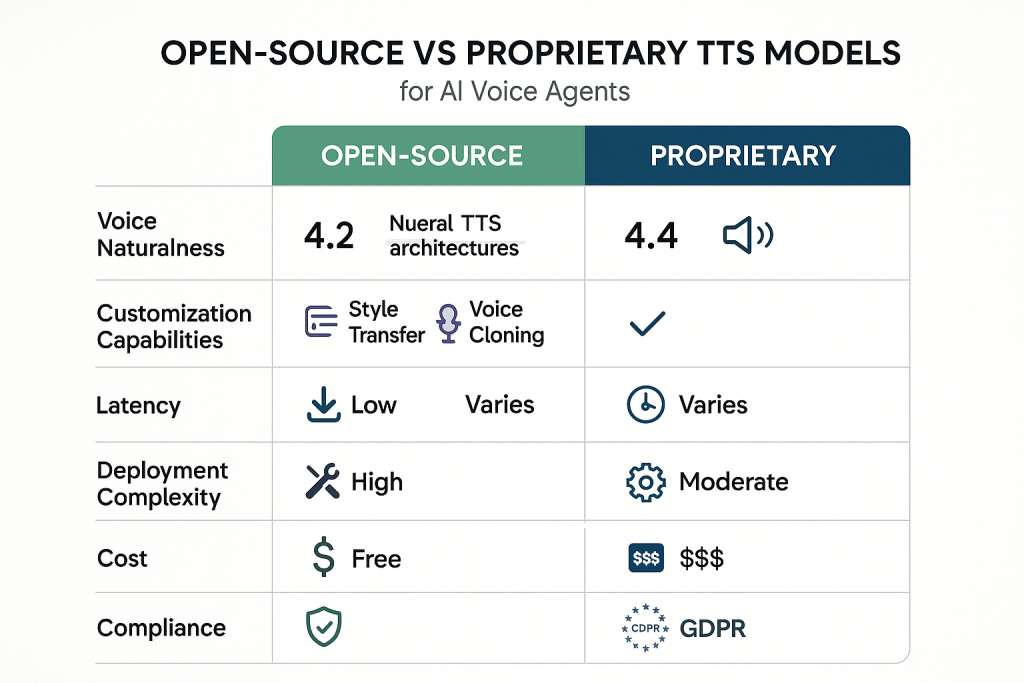
When it comes to TTS, you face a choice between open-source models and proprietary, commercially licensed solutions.
- Open-Source TTS: Offers maximum control, customization, and potentially lower costs. You can fine-tune models on your own data to create a unique brand voice. However, this requires significant in-house MLOps expertise to manage training, deployment, and scalability.
- Proprietary TTS: Provides a production-ready, scalable solution with guaranteed SLAs and commercial support. These are often easier to implement but offer less customization and can lead to vendor lock-in.
The right choice depends entirely on your team’s technical resources and strategic goals.
Chapter 4: The Holistic AI Voice Agent Architecture & Ethical Imperatives
These individual technologies don’t operate in a vacuum. They are part of a complex, real-time streaming pipeline. As the user speaks, audio data flows to the STT engine, the resulting text goes to the NLU model, the NLU output informs the response generation, and the final text is sent to the TTS engine to be synthesized and played back—often while the user is still talking. Achieving this with low latency (under 300ms for a natural feel) is a massive engineering challenge.
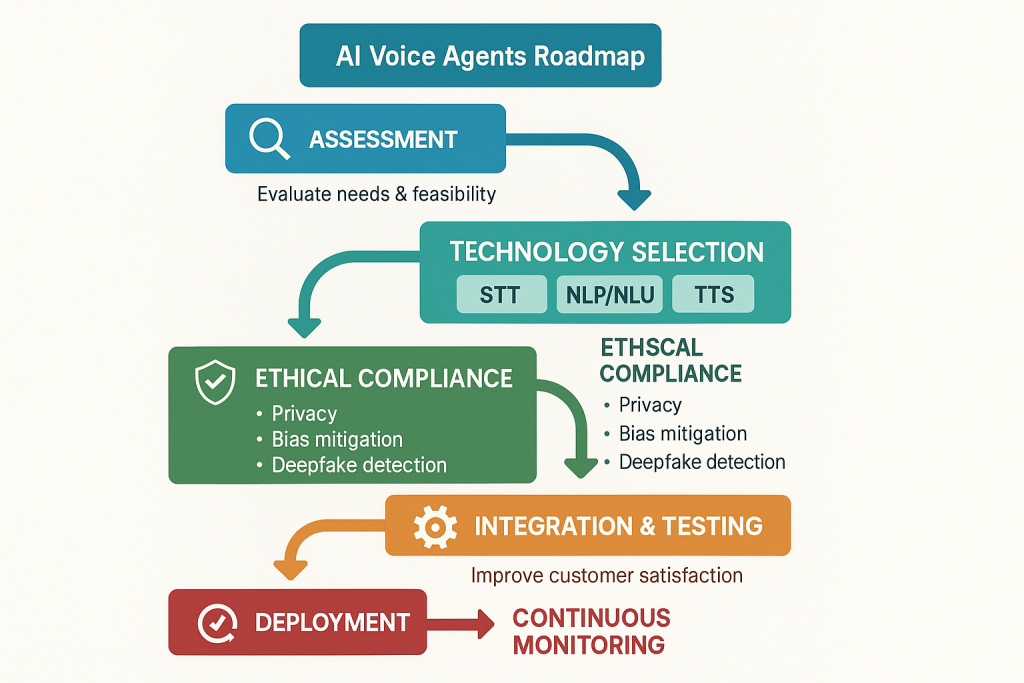
Beyond the technical architecture lies a foundation of ethical responsibility. Deploying voice AI isn’t just a technical decision; it’s a commitment to building trust with your users.
- Transparency and Disclosure: Users should always know they are speaking to an AI. Deception erodes trust and can have legal consequences.
- Data Privacy and Security: Voice data is biometric and highly sensitive. Your architecture must comply with regulations like GDPR, BIPA, and TCPA, ensuring data is secure, and user consent is properly managed.
- Bias and Fairness: AI models are trained on data, and if that data contains biases, the model will replicate them. It’s crucial to use diverse training datasets and continuously audit models for biased behavior.
- Deepfake Mitigation: The same technology that creates realistic TTS can be used maliciously. A responsible AI strategy includes measures to prevent the unauthorized use of voice clones and to detect deepfake audio.
Building an effective—and ethical—AI voice agent requires a holistic view that balances cutting-edge technology with robust safeguards.
Your Questions, Answered (FAQ)
How do I measure the ROI of investing in better voice technology?
Look at key business metrics. A more accurate STT system reduces transcription errors, leading to fewer escalations and faster call handling times—companies often see a 35% improvement. Better NLU increases first-contact resolution, boosting customer satisfaction by up to 30%. The overall impact can be a 20-30% reduction in operational costs.
What’s the real difference between a basic voice bot and a modern AI agent?
The difference is intelligence and context. A basic bot follows a rigid, predefined script. A modern AI agent, powered by an LLM, understands context, remembers past interactions, reasons through complex requests in real-time, and can generate novel, helpful responses it wasn’t explicitly programmed to say.
This seems too complex to build and manage in-house. What are my options?
You have a spectrum of options. You can use end-to-end platforms that handle the entire technology stack, or you can work with specialized providers for each component (STT, NLU, TTS). The key is to find a partner who can provide both the technical depth and the strategic guidance to integrate these powerful tools into your existing workflows.
How do we ensure our voice agent isn’t biased or unfair to certain customers?
This is a critical concern. It starts with the data. Your training data for STT and NLU must be diverse and representative of your entire customer base, including various accents, dialects, and speaking styles. The process also requires continuous auditing and testing of the live agent to identify and correct any biased or inequitable performance.
The Future is a Conversation
The technologies powering AI voice agents are evolving at an incredible pace. We’re moving toward proactive, autonomous agents that don’t just respond to commands but anticipate needs. Emerging speech-to-speech (STS) models are further reducing latency, enabling truly instantaneous, natural conversation.
Choosing the right technology stack is the first step. By understanding the core components—how they work, how to measure them, and how they fit together—you can cut through the noise and build a voice experience that delivers real value for your business and your customers.
Ready to explore how these technologies can transform your customer interactions? Let’s start the conversation. []